
Evaluations.
Retrieval benchmarks with the dataset, scoring and comparison systems named on each report.
BEIR text retrieval benchmark
September 2026Captain averaged 0.647 nDCG@10 on 1,271 queries over 66,454 documents. Cloudflare AI Search averaged 0.451, Gemini File Search 0.432 and Elasticsearch v8 0.386.
| nDCG@10 |  |  v8 |  File Search |  AI Search |
|---|---|---|---|---|
| Overall | 0.647 | 0.386 | 0.432 | 0.451 |
| SciFact | 0.887 | 0.610 | 0.685 | 0.681 |
| NFCorpus | 0.440 | 0.295 | 0.286 | 0.295 |
| FiQA | 0.616 | 0.254 | 0.325 | 0.378 |
| Queries returning results | ||||
| SciFact | 100% | 100% | 81%58 of 300 return nothing | 100% |
| NFCorpus | 100% | 100% | 90%32 of 323 return nothing | 100% |
| FiQA | 100% | 100% | 69%201 of 648 return nothing | 100% |
Indexing speed
| Time to index the corpus | ||||
|---|---|---|---|---|
| SciFact (5,183 documents) | 3 min | 10 s | 27 min | 73 min |
| NFCorpus (3,633 documents) | 2 min | 7 s | 18 min | 59 min |
| FiQA (57,638 documents) | 20 min | 60 s | 4.85 hrs | 40.1 hrs |
Captain runs at semantic ratio 1.0 with no reranker, the setting a sweep on 400 held-out queries picked; at its out-of-the-box defaults it averages 0.555. Cloudflare AI Search is at its defaults on the same corpora and queries. Elasticsearch v8 and Gemini File Search are the April 2026 run.
MRAG multimodal retrieval benchmarkApril 2026
MRAG multimodal
retrieval benchmark.
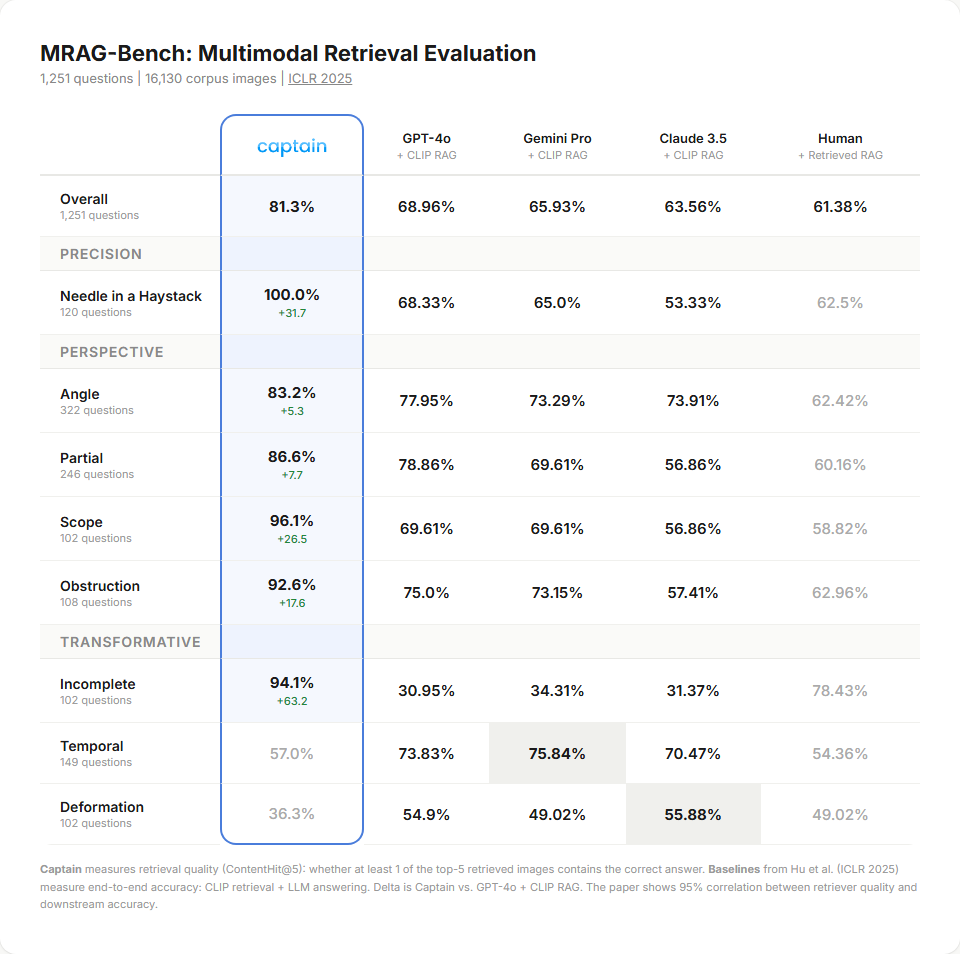
Captain on the MRAG-Bench multimodal retrieval evaluation from ICLR 2025: 1,251 questions over 16,130 corpus images.
- Captain81.3%
- GPT-4o + CLIP RAG68.96%
- Gemini Pro + CLIP RAG65.93%
- Claude 3.5 + CLIP RAG63.56%
- Human + Retrieved RAG61.38%
- Needle in a Haystack subset100%
Evaluation code and methodology: github.com/runcaptain/captain-mrag-bench
Captain Open RAG BenchmarkMarch 2026
Captain scored 95% retrieval accuracy on the Open RAG Benchmark with an LLM as judge, against 81% for a reranker RAG pipeline and 78% for vanilla RAG.
- Captain95%
- Reranker RAG81%
- Vanilla RAG78%
| Head to head | Accuracy | Win rate | Wins | Losses | Ties |
|---|---|---|---|---|---|
| Captain | 94.6% | 86.7% | 515 | 49 | 30 |
| Reranker RAG | 80.5% | 19.0% | 113 | 326 | 156 |
| Vanilla RAG | 78.5% | 15.9% | 95 | 348 | 156 |
| # | Bradley-Terry | Rating |
|---|---|---|
| 1 | Captain | 16571.570 |
| 2 | Reranker RAG | 1431-0.695 |
| 3 | Vanilla RAG | 1412-0.875 |
Method
- Four indexing strategies combined: multimodal embeddings, contextualized embeddings, BM25, full-text search.
- Embeddings normalised so semantic representations stay consistent across modalities.
- Chunk boundaries chosen with cosine-distance conditionals.